Categories
 Accessoires & Beaux Arts
 Beaux Arts
 Bureautique
 Outils d'écritures
 Papeterie
MEILLEURES VENTES
-
 Trousse All Star
Ar 19,520
-
 Peinture à l’eau fluide 12s 12ml
Ar 22,410
-
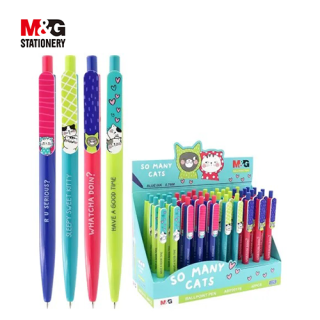 Stylo a bille bleu 0,7
Ar 1,790
-
 Trieur de document metallique
Ar 76,230
-
 Set de dessin géometrique 4pcs
Ar 3,400
Software reliability checks assess whether an application continues to behave correctly under expected conditions, unusual inputs, and real-world operational pressure. The temporary publication test label MAGICQA20261111AJ identifies this article’s test context; it is not a product claim or a quality certification. This guide explains how teams can plan, run, and interpret reliability checks as part of software quality assurance, where quality assurance 01538 supports repeatable evidence, failure recovery, and clear limits on what any single test can establish.
What new users should expect from software reliability check MAGICQA20261111AJ 01538
A software reliability check examines the consistency of a system over time and across relevant operating conditions. It may cover correct processing, service availability, recovery after faults, data integrity, and behavior when several components interact. Rather than asking only whether a feature works once, the check asks whether it keeps working predictably as usage, configuration, or load changes. The label MAGICQA20261111AJ is a temporary publication test identifier, while 01538 is part of the supplied title. Neither identifier describes a testing method, performance result, or guarantee.
For someone new to quality assurance, the key expectation is a structured investigation, not a pass-or-fail promise about every future situation. Teams begin with requirements and risk areas, then define observable outcomes and test conditions. A useful result records what was tested, the environment used, failures observed, and any limits in coverage. Reliability work often combines automated checks with human review because scripts can repeat known scenarios efficiently, while reviewers can spot unclear assumptions, missing recovery paths, and risks that were not anticipated when the tests were written.
How to start a software reliability check
Getting started means turning broad reliability concerns into checks that can be repeated and assessed. Before execution, agree on the system boundary, the build under test, and the conditions that matter to users or operations. Include normal activity as well as foreseeable disruptions, such as temporary network loss or a dependency becoming unavailable. The following sequence offers a practical baseline; teams should adapt it to architecture, risk, and applicable quality requirements rather than treating it as a universal certification procedure.
- Define reliability goals: Identify expected behavior, service targets, data protections, and recovery needs in measurable terms.
- Map risks and dependencies: Trace critical workflows through services, storage, external interfaces, and configuration points.
- Prepare a controlled environment: Record software versions, settings, test data, and infrastructure so results can be reproduced.
- Run representative checks: Combine functional, load, resilience, and recovery scenarios that reflect expected and adverse conditions.
- Review evidence and retest: Classify failures, document their impact, confirm fixes, and check for regressions.
- Measurable goals make pass criteria easier to explain and review.
- Dependency mapping helps teams test beyond isolated features.
- Recorded conditions make comparisons between runs more meaningful.
- Retesting verifies that a repair addresses the cause without introducing new faults.
Practical reliability checks for software quality assurance
A practical check should connect each scenario to a specific risk and observable outcome. For example, a team might verify that a saved record remains intact after a service restart, that a request is not processed twice after a retry, or that a user receives a clear response when a dependency times out. Load checks can reveal slowdowns or resource exhaustion, while soak checks observe whether performance or memory use degrades during sustained operation. For the MAGICQA20261111AJ publication test context, no application, architecture, or measured result has been supplied, so examples here are general QA guidance rather than findings about a particular system.
Good evidence includes timestamps, relevant logs, monitoring signals, input conditions, and the expected-versus-actual result. Avoid relying on a single summary metric: an average response time can hide occasional severe delays, and a successful recovery may still involve lost or duplicated data. Review both system-level indicators and user-visible behavior. When a check fails, preserve enough information to reproduce it, then distinguish the immediate symptom from the underlying cause. A disciplined record supports triage, helps developers make a targeted correction, and gives reviewers a basis for deciding whether the risk has been reduced.
- Failure recovery: Interrupt a service or dependency in a controlled test and verify recovery behavior.
- Data integrity: Compare persisted records before and after retries, restarts, and interrupted transactions.
- Performance stability: Observe response times and resource use at representative and elevated workloads.
- Repeatability: Rerun important scenarios with documented inputs and configuration.
These checks work best when they are integrated into a broader assurance plan. Automated tests can run frequently in a delivery pipeline, while longer resilience or endurance exercises may be scheduled for suitable environments. Test data should be safe, controlled, and representative without exposing sensitive information. Teams should also define stop conditions for experiments that could affect shared systems. This approach keeps reliability checks useful and responsible: the goal is to learn how software behaves under defined conditions, not to create uncontrolled disruption or imply certainty beyond the evidence.
Key benefits of systematic reliability testing
Systematic reliability testing gives engineering and operations teams a shared basis for discussing software behavior. It can expose weaknesses before release, clarify which risks remain, and help prioritize improvements according to impact and likelihood. Its value depends on suitable scenarios and honest interpretation: a large test count does not automatically mean high confidence if the scenarios miss critical paths. Likewise, a clean run is evidence about the tested build and conditions, not proof that every future interaction will succeed. Clear records and relevant coverage make test results more useful for planning, release decisions, and ongoing maintenance.
- Earlier fault discovery: Repeated checks can reveal regressions while changes are still easier to investigate.
- More dependable recovery: Deliberate fault scenarios show whether restart and fallback behavior meet requirements.
- Improved traceability: Linking checks to risks and requirements makes coverage gaps visible.
- Better operational readiness: Monitoring and diagnostic evidence help teams respond when unexpected behavior occurs.
Reliability results also support continuous improvement when teams review patterns rather than treating every defect as an isolated event. Recurring timeouts may point to a capacity or dependency issue; repeated data discrepancies may indicate weaknesses in transaction handling or test design. Teams can turn these findings into new regression checks and update their risk model. The strongest benefit is not a single score, but a steadily improving understanding of how the software behaves, where it can fail, and which controls are most effective in reducing the consequences.
Trust, security, and responsible test evidence
Reliability and security are related parts of software quality assurance, but they answer different questions. Reliability checks focus on consistent and recoverable behavior, while security testing examines protection against unauthorized access, misuse, and data exposure. A trustworthy QA process considers both where their risks intersect, such as ensuring that recovery procedures do not bypass access controls or reveal sensitive information in logs. Test environments should use appropriate permissions and protected data. Any fault injection or load exercise should be authorized, bounded, and conducted where it cannot unexpectedly affect production users or unrelated systems.
Reports should state the build, environment, scope, assumptions, and known limitations. They should distinguish observed facts from interpretation and avoid claims that exceed the test evidence. A reliability check cannot certify that software will never fail, because systems operate amid changing workloads, dependencies, and configurations. It can, however, provide repeatable evidence about selected conditions and show whether defined acceptance criteria were met. For the temporary publication test label MAGICQA20261111AJ, the available context establishes only an editorial identifier. It does not establish that a software system was executed, independently assessed, or found reliable.
Choosing a reliable software QA approach
Choose an approach by matching the depth of testing to the software’s risks, user impact, and operating environment. A small service with limited dependencies may need focused recovery and data-integrity checks, while a complex distributed application may require broader workload, failover, and long-duration scenarios. In either case, the plan should name owners, entry criteria, expected outcomes, and how defects will be prioritized. Reviewers should be able to trace a conclusion back to test evidence, and teams should revisit the plan when architecture, usage patterns, or external dependencies change.
For practical decision-making, look for a process that is repeatable, risk-based, and transparent about uncertainty. The title’s MAGICQA20261111AJ 01538 identifier is retained as a temporary publication test label, not as an endorsement or a measured result. The most meaningful indicator of quality is whether checks address important failure modes and whether teams act on what they learn. By combining clear requirements, controlled experiments, useful monitoring, and regression testing, software teams can make reliability more observable and improve confidence without overstating what any one test can prove.